AI systems that aren't rigorously evaluated introduce hidden risks like inaccurate outputs, biased decisions, and inconsistent performance that only surface after deployment. Fusefy empowers organizations to continuously test, benchmark, and validate AI models across accuracy, safety, fairness, and performance before they reach production.
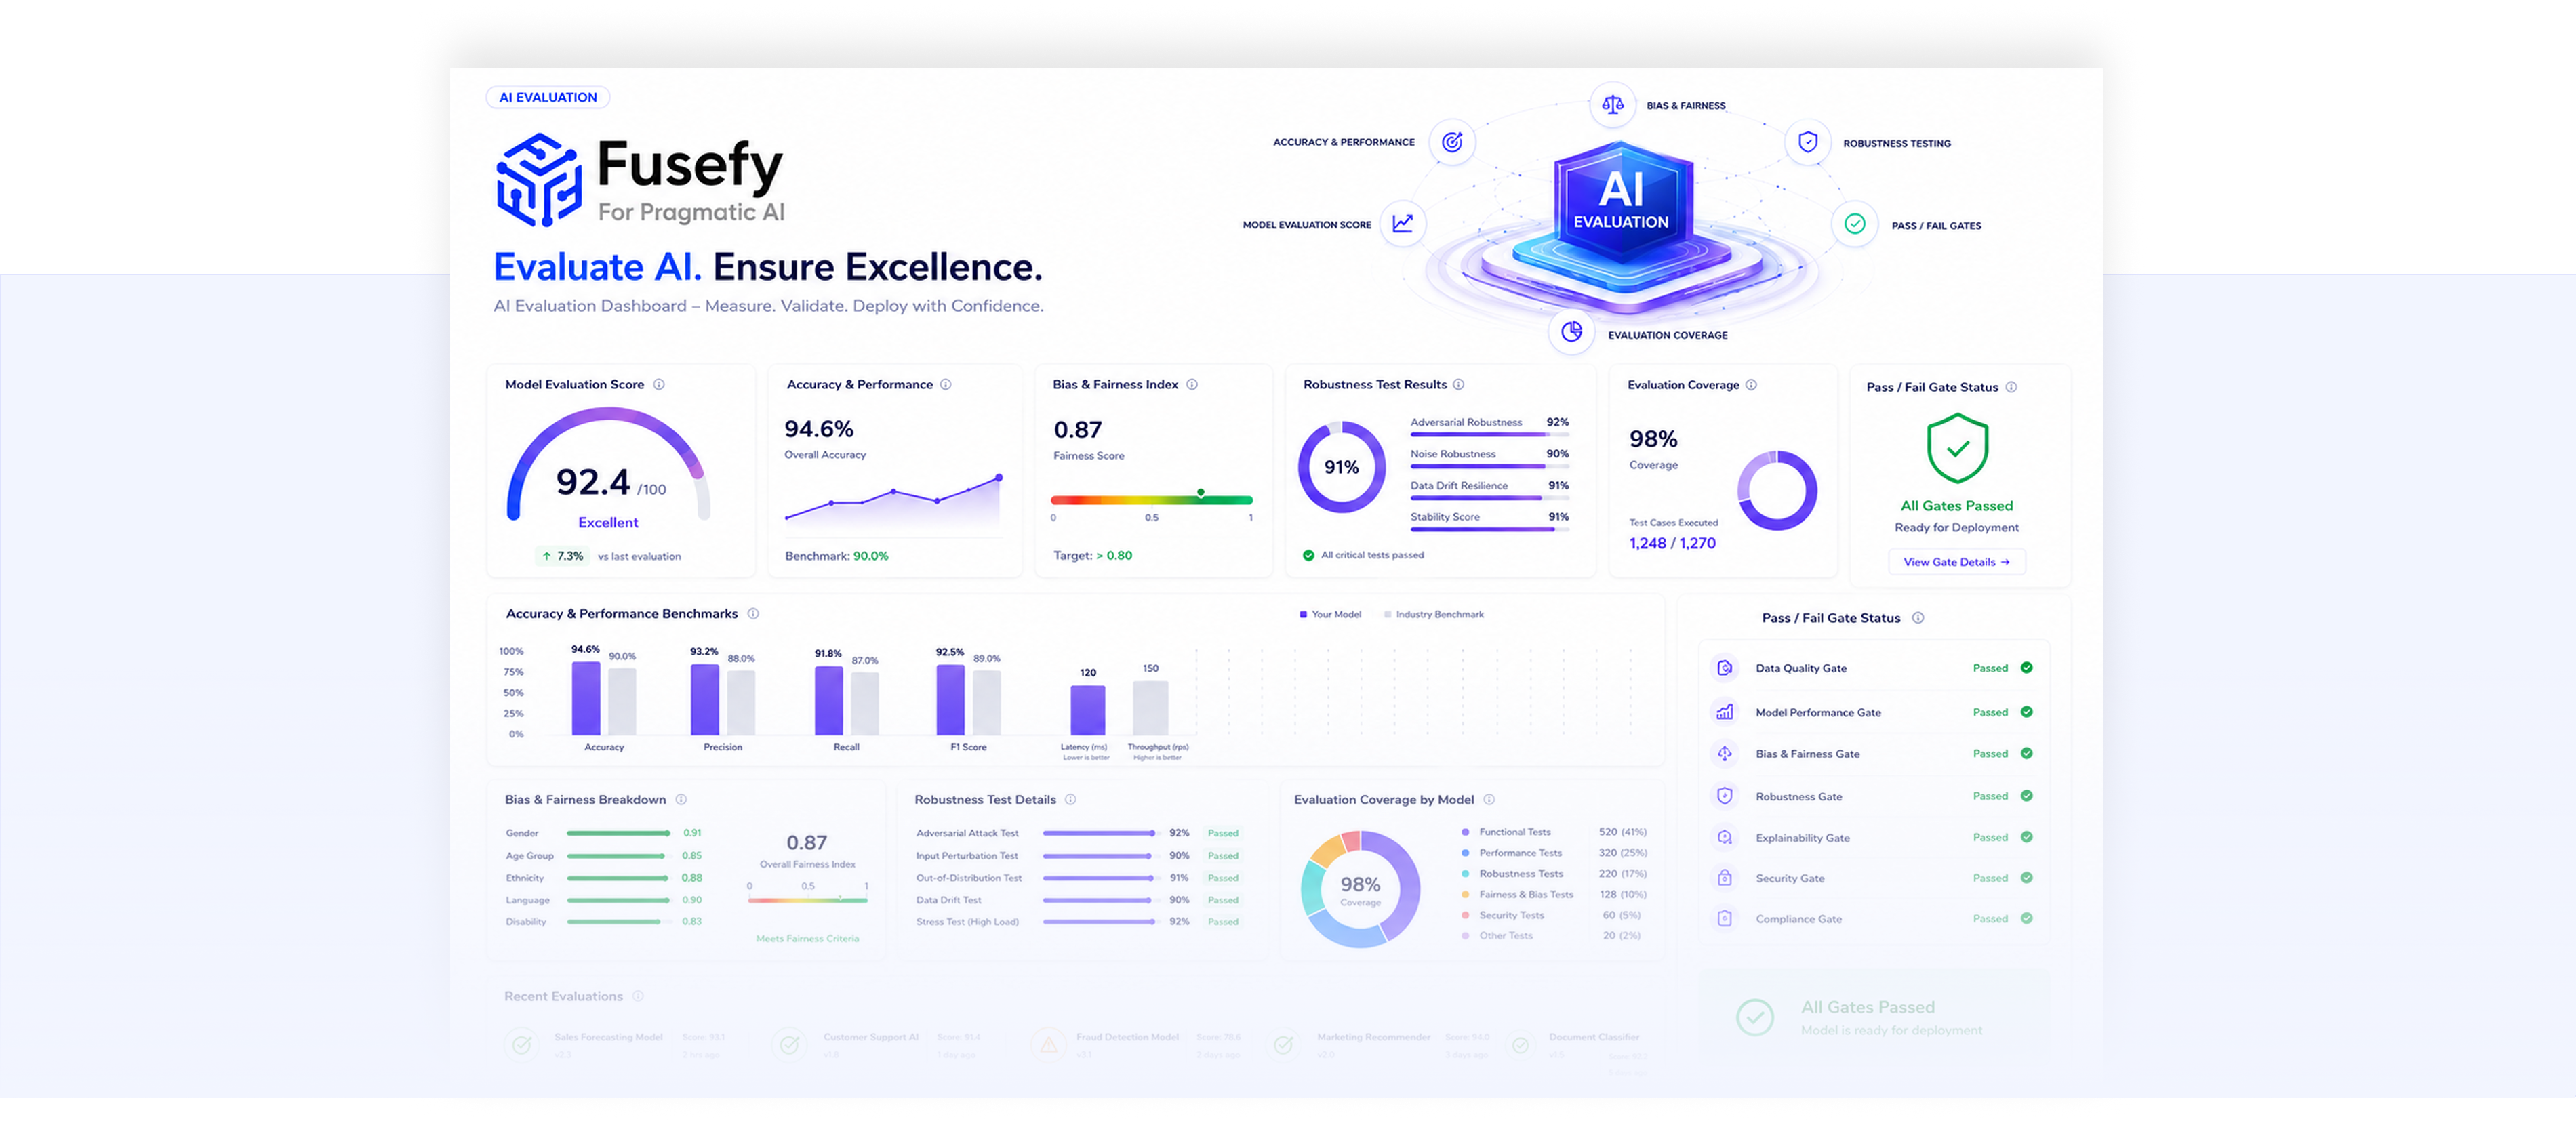
Evaluating AI is a continuous, staged process that validates models from development through production. Fusefy brings every stage of evaluation into a unified workflow, helping organizations move from ad-hoc testing to systematic, repeatable validation.
The Evaluation Process
Curate and maintain high-quality, representative golden datasets with verified ground-truth outputs, covering standard cases, edge cases, and high-risk scenarios to serve as the benchmark for evaluation.

Rigorously test models and agents against the golden dataset before release — measuring accuracy, bias, hallucination rate, and robustness for models, plus task completion rate, tool-call accuracy, and multi-step reasoning consistency for agents to generate a pass/fail scorecard that gates deployment decisions.

Track live model and agent performance post-deployment detecting drift, degradation, token-efficiency loss, and emerging risks in real time and trigger re-evaluation cycles to keep systems reliable over time.
Agents produce outputs and take action. That makes assurance more than a model level exercise. Fusefy evaluates the full agentic stack, including the underlying model, prompts, tools, workflows, memory, decisions, and actions, helping enterprises understand risk and validate agent behavior across the AI lifecycle.
Tests the orchestration layer an agent runs inside: guardrails, fallback logic, and tool permissions, verified under real conditions.
Purpose-built metrics for autonomous workflows: task completion rate, tool-call accuracy, and multi-step reasoning consistency.
Validates that agents use resources appropriately, catching cost-inflating inefficiencies before they scale in production.
By providing structured, stage-based testing, standardized scorecards, and continuous post-deployment monitoring, Fusefy empowers teams to deploy AI with evidence-backed confidence.
Whether you're validating your first model or evaluating hundreds of AI systems across the enterprise, Fusefy helps you catch failures before they reach users, accelerate deployment cycles, and build AI systems that perform reliably at scale.
 Speak to an AI Evaluation Expert